This guide is for platform operators maintaining an installation. Use the administrator portal for platform health and lifecycle evidence. For a tenant’s application charts and logs, see Worker observability.
Inspect platform health
Platform operators use Platform → Overview for platform-owned volume and service posture, Fleet for host pressure and placed-service readiness, and Events & logs for lifecycle evidence and selected service logs. These views avoid mixing every tenant’s detailed charts into one dense dashboard.
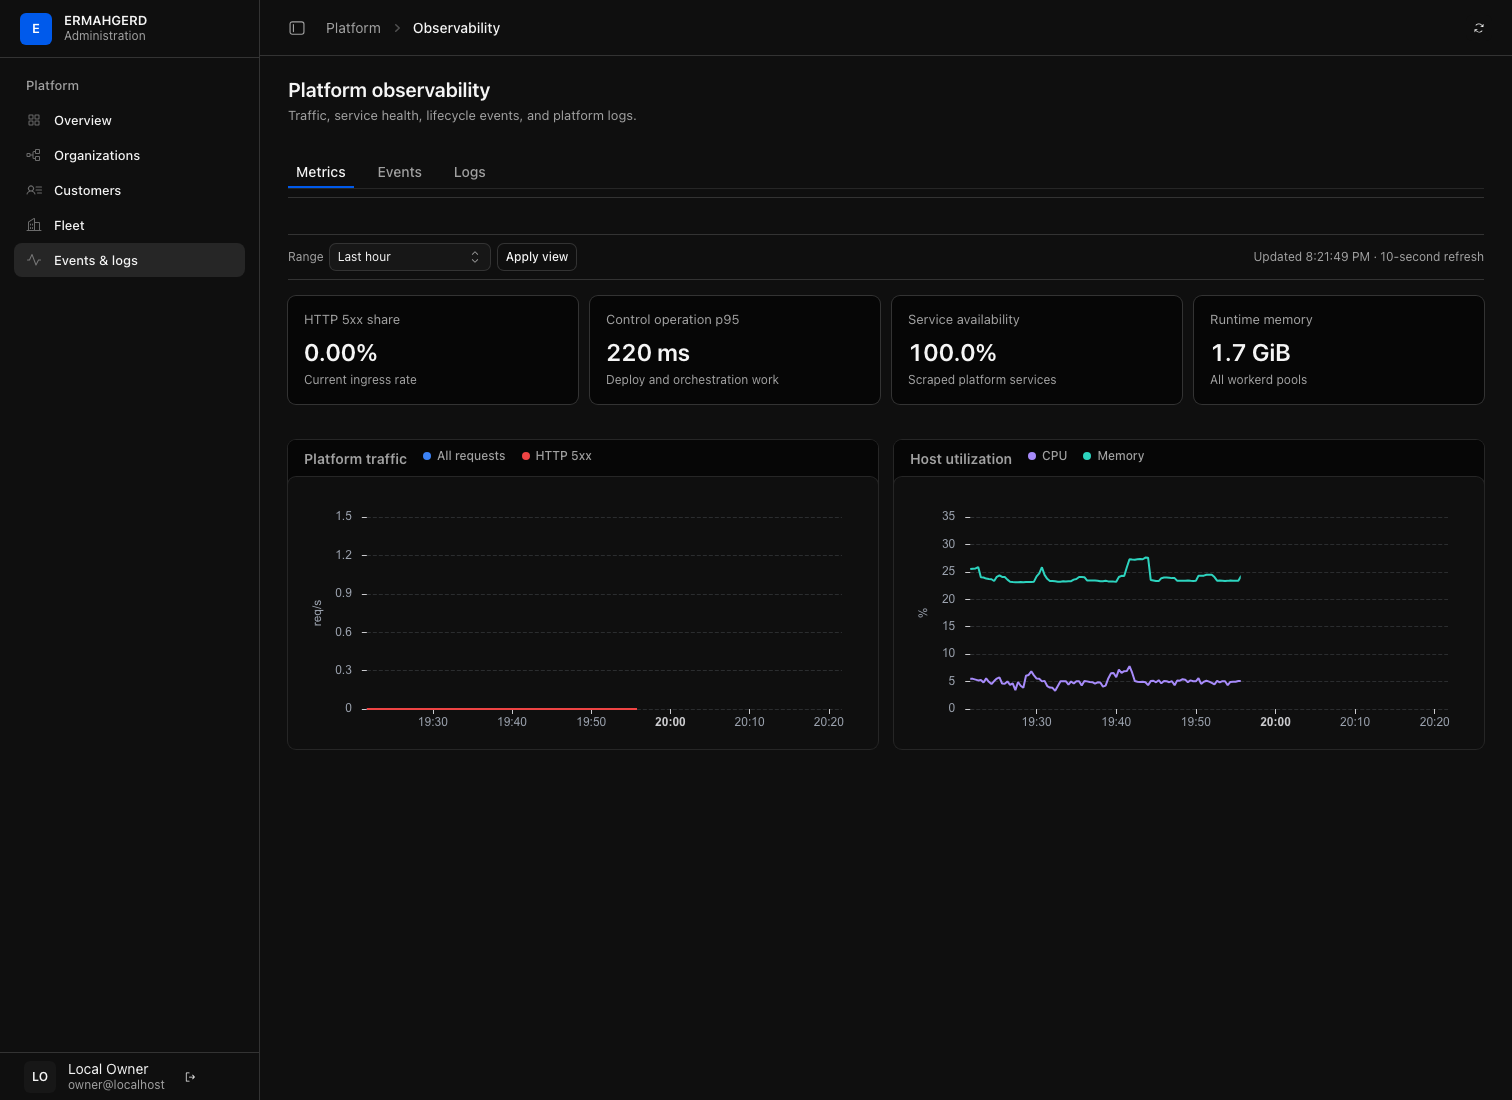
Prometheus, Loki, Tempo, and Grafana are preconfigured for deeper operator investigation. Their dashboards are recreated during provisioning, so an operator can investigate a newly created appliance immediately without carrying forward observability data from an older fleet.
The rollout objectives are bounded measurements rather than continuous SLIs. The deterministic compute canary requires 99.99% correct responses within 250 ms. The integrated profile separately requires 99.99% correct R2 write/read-back plus durable queue acceptances within 250 ms. Series are kept distinct by test ID so separate deployment runs are not accidentally merged into a synthetic long-term window.
Queue delivery service level
The current platform objective is: 99.99% of messages accepted by a queue with a configured consumer receive their first delivery attempt no later than the configured batch window plus 250 ms, measured over a rolling 24 hours.
The deadline starts when a durably accepted message becomes eligible for delivery. Requested delivery delay and intentional batch collection time are therefore excluded. A message is evaluated once against its stored deadline; missing messages remain bad events even when no attempt was observed. Retries do not reset the deadline. Consumer execution and acknowledgement latency are shown as context but remain the Worker author’s responsibility and are not part of this scheduling SLI. Queues without a consumer are ineligible rather than counted as failures, and no eligible traffic produces no SLI value rather than a synthetic pass.
Prometheus recording rules calculate 5-minute, 30-minute, 1-hour, 6-hour, and 24-hour windows. Fast-burn and slow-burn alerts are evaluated in Prometheus and shown in Grafana. The appliance does not configure an external Alertmanager, so these alerts are diagnostic state rather than outbound notifications.
Storage service levels
The service-level dashboard has independent read availability and write availability objectives of 99.99% over a rolling 24 hours. Reads enter success counts only after the body completes with the expected length. Writes enter success counts after blob storage and metadata commit succeed. Fast failures, truncated streams, internal exceptions, disk exhaustion, and operations left unfinished by a storage-process restart count as failures. Explicit client cancellations, expected user results such as missing keys or failed conditions, and configured tenant-quota rejections are recorded separately and excluded.
Read first-byte and write finalization objectives currently use candidate
thresholds of 5 ms and 25 ms, respectively. Latency attainment and budgets are
visible, but latency burn alerts are disabled pending baseline evidence.
storage_read_target_ms, storage_write_target_ms, and
storage_latency_slo_enabled control this policy in Ansible. Each latency
series includes its threshold so changing the target does not combine different
policies. Availability burn alerts are enabled immediately.
The service timer starts at the authorized GET/PUT object handler, before its catalog and blob work. First-byte timing ends when the first object-body chunk is available; only one chunk is prefetched, preserving streaming and backpressure. Empty objects use end-of-stream availability. Finalization starts when the last upload byte is consumed and ends at successful acknowledgement preparation. Total duration and transferred bytes remain available to reveal slow uploads, downloads, and storage backpressure. Bytes are exported when an operation settles, not continuously during long transfers.
The current scope is object GET (including ranges) and single PUT through S3, Worker bindings, or the console. HEAD operations are diagnostic only; copy, list, delete, and multipart operations are outside these initial objectives. S3 authentication, ingress transport, and Worker-adapter buffering are outside the service timer and are included in caller measurements. No claim of replicated durability or power-loss safety follows from an acknowledgement SLI.
A separate Durable Object records operation starts and terminal results in SQLite. It resolves unfinished operations as interrupted on the next process invocation, including when the metrics endpoint is the first request after a restart. A running but stuck request remains visible as pending, with an oldest-pending-age alert; it is never counted as successful. Missing storage scrapes have their own coverage alert. Requests that cannot reach the service are outside its counters and must be detected by ingress/probe observations.
On a disposable local demonstration, run the isolated storage benchmark with:
make storage-benchmark
STORAGE_ITERATIONS=200 STORAGE_CONCURRENCY=8 make storage-benchmark
It creates a uniquely named probe Worker and bucket, deploys the Worker through Wrangler, and measures S3 and R2 bindings under mixed 4 KiB, 64 KiB, and 1 MiB read/write traffic. Each object is read twice and verified byte-for-byte. The report separates caller first-byte/total latency from exact service-level counter deltas and checks that every measured read/write appears in those counters. This is a closed-loop, configurable-concurrency benchmark, not a fixed-rate traffic profile. Caller measurements include connection setup.
A separate serial phase uses fsync and POSIX_FADV_DONTNEED on only that
run’s probe blobs, then compares cache-advised reads with repeated reads. It
does not drop global caches or touch other buckets. These are not guaranteed
disk-cold measurements: guest eviction is advisory, and host/device caches
are uncontrolled. A short successful run does not establish four-nines
reliability. Evidence is saved under artifacts/performance/storage-*/.
Probe objects are individually deleted and temporary credentials revoked; the
empty probe bucket and Worker remain identifiable for inspection.
Collection and retention
Alloy collects VM, process, systemd, runtime cgroup, control-plane, storage, queue, and HAProxy metrics; it forwards selected journals to Loki and OTLP traces to Tempo. Beyla adds eBPF HTTP and network observations for HAProxy and the runtime pool. The control plane emits deployment, validation, activation, proxy-publication, rollback, and recovery events as traces and structured lifecycle records.
Ingress records use a bounded HAProxy ring and guest-loopback RFC5424 transport to Alloy. Paths exclude query strings and are bounded; request bodies, cookies, and authorization headers are not collected. The channel can lose records during collector failures or buffer overflow.
Prometheus retains seven days or 8 GB; Loki and Tempo retain seven days.
Telemetry persists across make down and is discarded with make destroy.
Validate on a disposable installation
The following repository targets use the local demonstration profile, create test resources, and may redeploy probe Workers. They are not commands for investigating a live customer’s deployment. Run them separately from provisioning and use their retained evidence to compare platform changes.
make observability-check       # verify stored metrics, logs, traces, Grafana
make telemetry-check           # deploy tenant fixtures and check isolation
make load                      # 60 seconds at 10 requests per second
RATE=100 DURATION=120s make load
make load-update               # run both continuity profiles below
make load-sum-update           # compute-only canary across three Wrangler deployments
make load-services-update      # R2 + queues across three Wrangler deployments
make load-sum-update uses the deterministic sum Worker as a platform canary.
Its thresholds require correct responses, no dropped iterations, p95 below
250 ms, p99 below one second, and at least 99.99% correct responses within
250 ms. It deliberately does not make arbitrary tenant Worker response time a
platform SLO. Results, k6 samples, deployment intervals, lifecycle records,
and reports are saved beneath artifacts/performance/.
make load-services-update deploys the dedicated rollout-services probe through
Wrangler. At a constant 10 new jobs/second, each HTTP invocation writes a unique
R2 object, reads it back for correctness, then durably enqueues a job. The queue
handler reads the same object, verifies its document, writes an idempotent receipt,
and acknowledges. Both handlers belong to the deployed Worker, so the three
revisions exercise HTTP and native queue delivery cutovers while work is pending.
Receipt polling adds HTTP traffic beyond the 10 job submissions/second.
The services probe has its own 99.99%-within-250-ms acceptance check; it does not feed the compute-only canary SLI. Queue completion is measured separately: every accepted job must have a matching receipt within 10 seconds, and queue counters must reconcile with accepted jobs after draining. Reports include R2 round-trip and enqueue latency, receipt-observation p50/p95/p99/max, retries, consumer version counts, and queue backlog/oldest-age snapshots taken approximately every second. Receipt latency includes the 200-ms polling interval and R2 read, not just handler execution. These are bounded, synthetic regression checks, not a general promise about arbitrary application latency or exactly-once delivery.
The service profile uses the test-only rollout-probes bucket/queue and
rollout-probes-dlq, refuses to start with pending primary-queue work or a foreign
consumer, and serializes local runs. It never purges existing messages. Objects
are retained under run-specific probes/services-rollout-<id>-<iteration>/
prefixes for diagnosis. Do not use these fixture names for application data.
Detailed reconciliation is in services-report.json; queue-samples.json and
the usual k6, Loki, Tempo, and Prometheus artifacts share its run directory.
RATE, DURATION, DEPLOY_COUNT, and DEPLOY_INTERVAL_SECONDS configure either
profile. Leave enough duration after the last deployment to observe its handlers.